Integrating Large Language Models (LLMs) in 2026: The OpenAI and Claude APIs for Developers
How to call the OpenAI and Anthropic Claude APIs, which models are current in September 2026, and a worked cost example covering prompt caching, output length and model choice.
A support assistant on Claude Sonnet 5 that answers 1,000 questions a day costs 11 dollars a day at list prices. Two changes bring that down to 3.46 dollars, and neither of them replaces the model. The calculation comes further down. It only makes sense once the first API call works and you know which models are on offer.
This guide covers those steps in that order, for OpenAI and for Anthropic, with Python examples. Model names and prices were checked against the providers’ documentation on 28 September 2026. They go stale quickly: on 23 October 2026 alone, OpenAI retires 17 models and model variants (deprecations).
Which Models Are Current in September 2026
OpenAI lists its current models in the model catalogue, Anthropic in its models overview. Seven models appear on those two pages:
| Provider | Model | API ID | Context | Input / output per million tokens |
|---|---|---|---|---|
| OpenAI | GPT-6 Astra | gpt-6-astra |
1.05M | $10 / $50 |
| OpenAI | GPT-6 Sol | gpt-6-sol |
1.05M | $2 / $10 |
| OpenAI | GPT-6 Luna | gpt-6-luna |
1.05M | $0.10 / $0.50 |
| Anthropic | Claude Fable 5.1 | claude-fable-5-1 |
1M | $10 / $50 |
| Anthropic | Claude Opus 5.5 | claude-opus-5-5 |
1M | $4 / $20 |
| Anthropic | Claude Sonnet 5 | claude-sonnet-5 |
1M | $2 / $10 |
| Anthropic | Claude Haiku 4.5 | claude-haiku-4-5-20251001 |
200K | $1 / $5 |
On every one of the seven, an output token costs exactly five times as much as an input token, which decides where saving pays off later on. GPT-6 Astra also carries a surcharge for very long prompts. Above 272,000 input tokens, the whole request is billed at twice the input rate and 1.5 times the output rate (GPT-6 Astra model page).
Claude Opus 5 shows how briefly a model stays on top. Anthropic released it on 24 July 2026. Two months later it has dropped out of the overview, and its model page suggests moving to Opus 5.5. At OpenAI, the GPT-5.6 family (gpt-5.6-sol, gpt-5.6-terra, gpt-5.6-luna) has moved from the catalogue to the full model list. It remains available, and OpenAI names it as the substitute for most of the models being retired.
Retirements are announced ahead of time. OpenAI removed gpt-4.5-preview, which earlier versions of this guide recommended, on 14 July 2025. The 23 October 2026 list includes o1, o1-pro, o4-mini, gpt-4-turbo and the image model gpt-image-1; the dated snapshots of gpt-5, gpt-5-mini, gpt-5-nano and o3 follow on 11 December 2026. Anthropic shut down claude-3-5-sonnet-20240620 on 28 October 2025, Claude 3.5 Haiku on 19 February 2026, and Claude Opus 4 and Sonnet 4 on 15 June 2026 (model deprecations).
So keep the model name in configuration, an environment variable for instance, and out of the source code. The examples below hard-code it only to stay short.
Your First Call to the OpenAI API
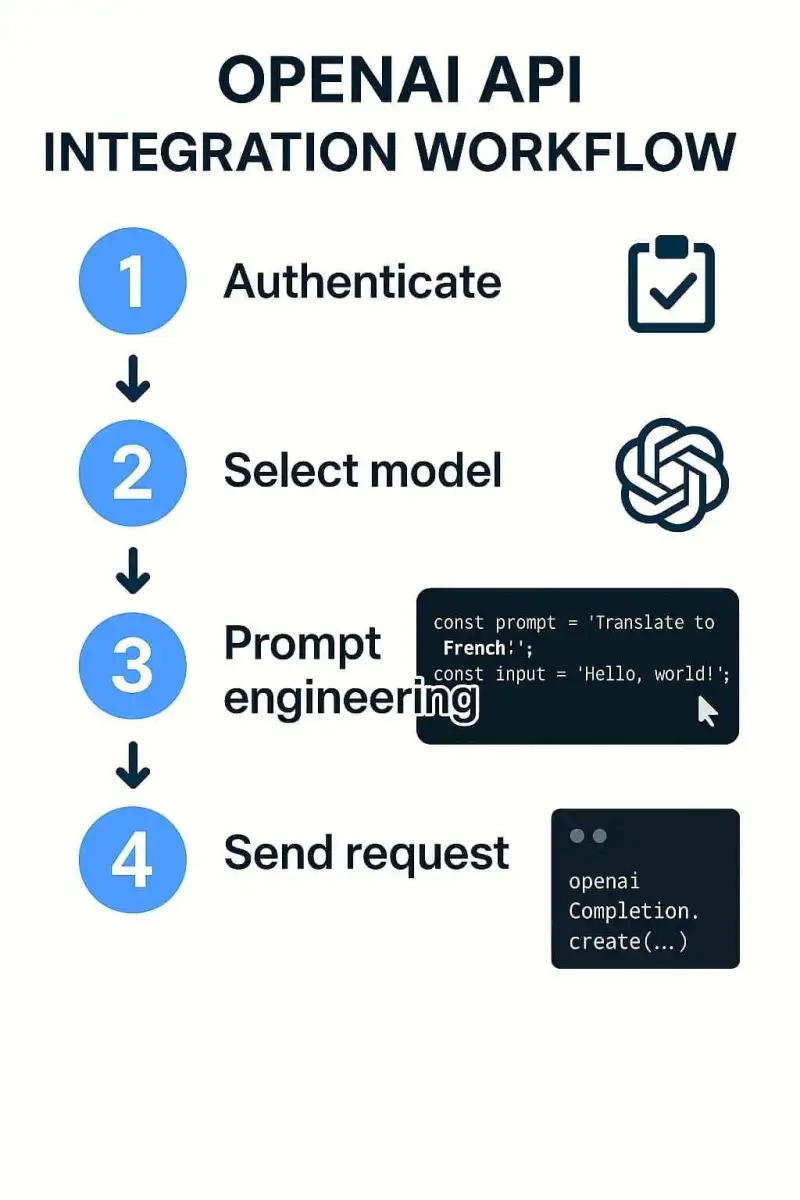
OpenAI has two endpoints for text generation. Chat Completions is the older one and is still supported, but OpenAI recommends the Responses API for all new projects (migration guide). The example uses Chat Completions because it is the shortest form and sits well next to the Anthropic call further down. If you are starting from scratch, start with Responses.
gpt-5.6-sol, the model in the example, is no longer the newest but still available. In the GPT-6 family, the parameter reasoning.effort sets how much compute goes into an answer: none to max for Sol and Luna, low to max for Astra.
Prerequisites
an OpenAI API account and an API key, read here from the environment variable
OPENAI_API_KEYthe Python package
openaiworking knowledge of Python, HTTP and JSON
# OpenAI API basic integration
import os
from openai import OpenAI

# Initialize client
client = OpenAI(
    api_key=os.environ.get("OPENAI_API_KEY")
)

# Send request to the model
response = client.chat.completions.create(
    model="gpt-5.6-sol",
    messages=[
        {"role": "system", "content": "You are a helpful assistant."},
        {"role": "user", "content": "Explain the benefits of APIs in simple terms."}
    ]
)

# Output response
print(response.choices[0].message.content)
What the Responses API Gained in May 2025
On 21 May 2025, OpenAI gave the Responses API a set of built-in tools that Chat Completions lacks (announcement). It can call tools hosted on remote Model Context Protocol servers, so an agent-style application no longer needs an adapter layer of its own. Code Interpreter and image generation run as tools inside the API. Background mode handles long jobs asynchronously instead of letting them run into a request timeout. The same release brought reasoning summaries and, for Zero Data Retention customers, encrypted reasoning items that can be reused across requests without OpenAI storing them.
Names age here too. gpt-image-1, the image model introduced that day, is on the list for 23 October 2026, with gpt-image-2 as its substitute.
Your First Call to the Claude API
Anthropic’s interface resembles OpenAI’s, and porting code between them means changing three things (API reference). Requests go to POST /v1/messages. The system instruction is a top-level system field, because the message list has no “system” role. And max_tokens is required, so every request states an upper limit for the answer.
If you plan to use both providers, put a thin layer of your own between them and the application before the calls spread through the codebase. Adding one afterwards is tedious.
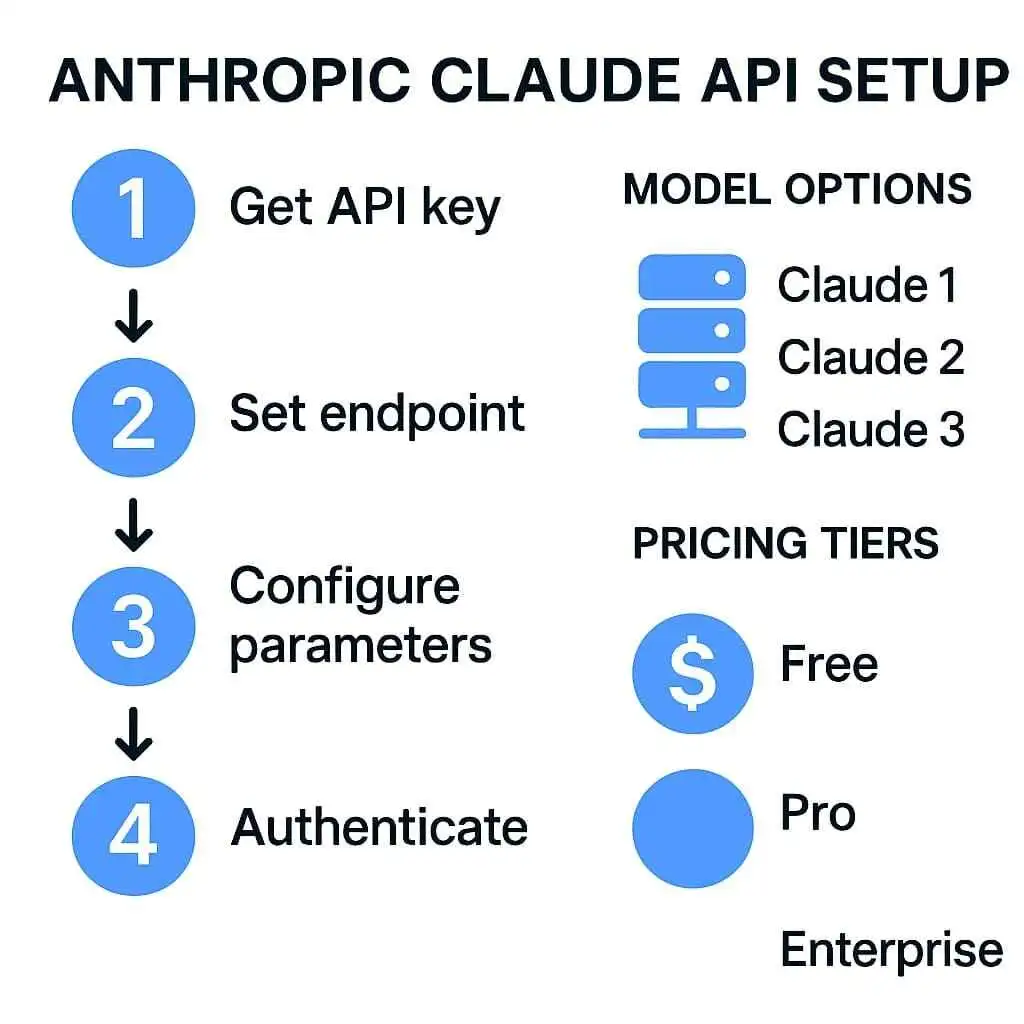
The example uses Claude Sonnet 5, which Anthropic’s pricing page describes as the best combination of speed and intelligence. The key comes from ANTHROPIC_API_KEY, and the Python package is called anthropic.
# Claude API basic integration
import os
import anthropic

# Initialize client
client = anthropic.Anthropic(
    api_key=os.environ.get("ANTHROPIC_API_KEY")
)

# Send request to Claude
message = client.messages.create(
    model="claude-sonnet-5",
    max_tokens=1024,
    messages=[
        {"role": "user", "content": "Explain the benefits of AI integrations for developers."}
    ]
)

# Output response
print(message.content[0].text)
What a Call Costs: A Worked Example
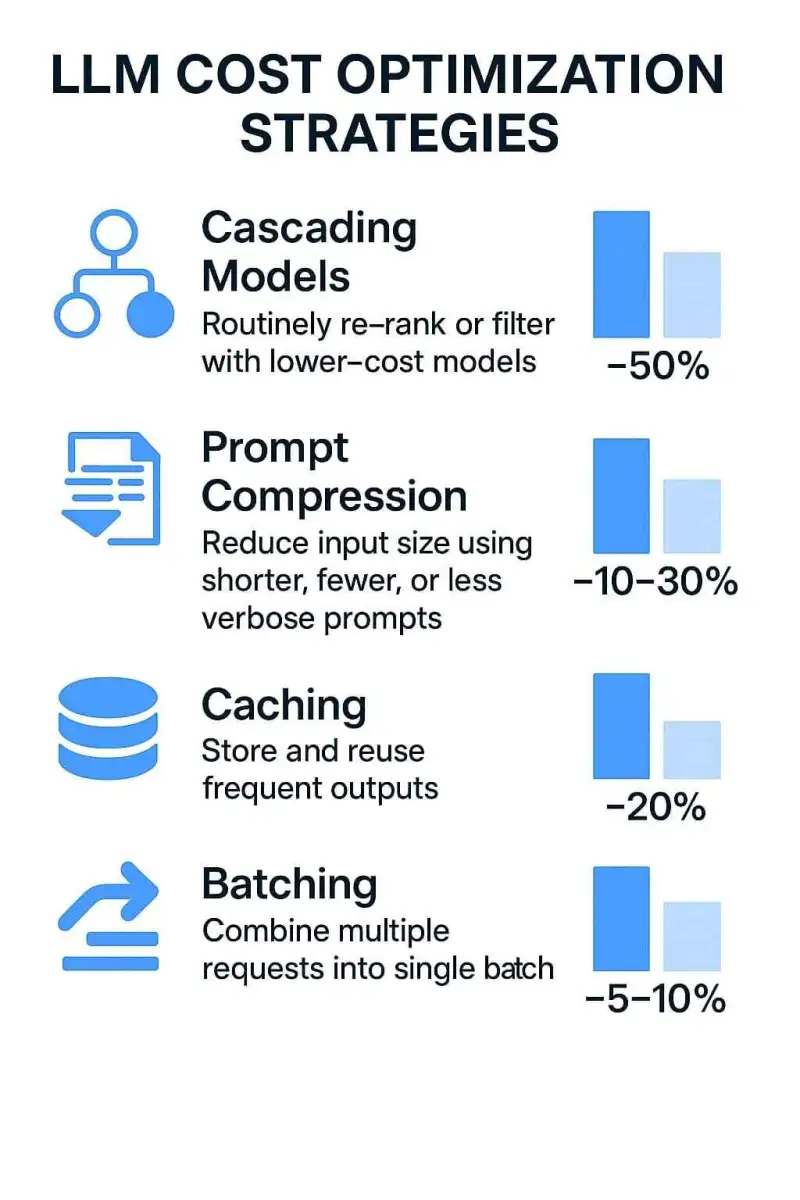
Both providers bill per token, with input and output priced separately. The assistant from the introduction makes the levers comparable. It runs on Claude Sonnet 5 and handles 1,000 requests a day, each consisting of a fixed 2,800-token system prompt and a 200-token user question, with a 500-token answer. Prices are taken from Anthropic’s pricing page.
Baseline. Three million input tokens at 2 dollars per million come to 6.00 dollars, and 500,000 output tokens at 10 dollars per million to 5.00. That is 11.00 dollars a day.
With prompt caching. The 2.8 million tokens of the fixed prompt are read from cache at 0.20 dollars per million, or 0.56 dollars. The questions still cost full price, 0.40 dollars. With output unchanged, the day costs 5.96 dollars.
Answers capped at 250 tokens as well. Output falls to 2.50 dollars and the total to 3.46 dollars, a little under a third of the baseline.
For comparison, Claude Haiku 4.5 without caching. 3.00 dollars of input plus 2.50 of output make 5.50 dollars.
After step 2, output accounts for 5.00 of the 5.96 dollars, or 84 percent. Because output costs five times the input rate on every model in the table, answer length is the largest item left once the prefix is cached. Switching to Haiku in step 4 saves about as much as the cache, provided the smaller model handles the task equally well. In this example the two cannot be combined, though. Haiku 4.5 only caches prompts of 4,096 tokens or more, and a shorter fixed part is processed uncached, without an error message.
Prompt Caching: What Is Actually Billed
The example assumes the cache stays warm. At Anthropic an entry lives for five minutes by default and is refreshed at no extra cost on every hit (prompt caching documentation). 1,000 requests a day average one every 86 seconds, but whenever more than five minutes pass between two of them, the entry has to be written again. A write costs 1.25 times the input price, 0.7 cents in the example compared with 0.056 cents for a read. The one-hour variant costs twice the input price to write. Reads are billed at a tenth of the input price on most Claude models, at a twentieth on Opus 5.5 and at a fortieth on Fable 5.1.
Since GPT-5.6, OpenAI follows the same pattern: writes at 1.25 times and reads at 0.1 times the input price, a minimum of 1,024 tokens and a default lifetime of 30 minutes (prompt caching guide). Older models carry no write charge, and their read discount depends on the model, up to 90 percent. GPT-6 Sol has the same list prices as Claude Sonnet 5, so the worked example comes to the same amounts there, except that the longer lifetime means fewer rewrites.
A cache hit requires an unchanged beginning of the prompt. Instructions and examples that never change go first, everything that varies goes last.
Capping Output and Context
You can limit answer length in two ways, with an instruction in the prompt and with the hard cap max_tokens. The cap alone stops generation once it is reached, if need be mid-sentence, so state the length you want in the prompt as well.
On the input side, two habits pay off. Instructions that appear in both the system message and the user message are paid for twice. And of the available context, send only what this particular request needs.
LLM Cascading
A cascade sends a query through a chain of models, cheapest first. Only when that answer fails a checking stage does the query move on to a more expensive model. Lingjiao Chen, Matei Zaharia and James Zou described the approach in FrugalGPT, submitted on 9 May 2023. According to the abstract, it matches the best single model of the time, GPT-4, at up to 98 percent lower cost, or improves accuracy over GPT-4 by 4 percent at the same cost.
Read the 98 percent as a case for the method rather than a forecast. It was measured with 2023 models at 2023 prices. What remains in your own application depends on the checking stage. If it lets weak answers through, the chain saves money at the expense of quality; if it rejects too many, a large share of requests is paid for twice.
RAG and Semantic Caching
Retrieval-augmented generation (RAG) passes the model only the relevant passages from a data source instead of sending a large context with every request. How much that saves depends on the size of the whole corpus relative to the excerpt actually needed, so there is no general figure. Retrieved passages change from one request to the next and therefore belong after the fixed, cached part of the prompt.
Semantic caching works one level up. It answers recurring questions from a store of your own without calling the model at all, whereas the providers’ prompt caching only makes the call cheaper.
Prompt Engineering for Developers
Prompt engineering means phrasing the input so that the model gets the task right the first time. The link to cost is direct: every answer that needs correcting costs a second call.
Zero-Shot vs. Few-Shot Prompting
Zero-shot prompting gives the model the instruction alone, with no example. For clearly bounded tasks that is enough.
Few-shot prompting puts two to five input-output pairs in front of the task. It helps most with format constraints: if the answer must be a JSON object with fixed keys, one worked example convinces the model more reliably than three sentences of description. The examples travel with every call and add tokens. Placed in the fixed part of the prompt, they are read from cache just like the system prompt in the worked example.
Five Rules for Prompts
Context before instruction. The model knows neither your data model nor your naming conventions. Whatever it needs to know belongs in the prompt.
Show the format instead of describing it. One example of the desired output beats any explanation.
Split large tasks. Two calls with a clear scope deliver more reliably than one meant to do everything at once. The same holds for coding assistants, as the guide to GitHub Copilot and Cursor shows.
Fixed parts first. Instructions and examples that never change go at the start of the prompt. Only then does the cache apply.
Refining means measuring. Without a small set of test cases, every prompt change remains a guess.
Summary
Four points decide more about an LLM integration than the choice of provider.
Model names belong in configuration. Both providers retire models on a schedule, with notice and without exceptions. At OpenAI, 17 models and variants go on a single day, 23 October 2026.
Cache first, then trim. In the worked example the cache nearly halves the bill, and most of what remains is output.
Cascading needs a checking stage you trust. Without one, the chain only pushes the error further back and pays for it twice.
Prompts need test cases. Otherwise there is no telling whether a change helped or was merely different.